Think back to when you were a small child. How did you learn what a dog is?
Nobody sat you down and said: "A dog has four legs, fur, a tail, and barks. If an animal matches all four, it is a dog." That rule wouldn't even work. Cats have four legs, fur and a tail too.
Instead, something simpler happened. You saw a dog, and someone said "dog!". Then another one. A big one, a tiny one, a brown one, a fluffy one. Sometimes you pointed at a cat and said "dog!", and someone corrected you: "No, that's a cat."
After enough examples and corrections, your brain just knew. You could spot a dog you had never seen before.
That's exactly how machine learning works.
In #001 we said AI is software that learns patterns from examples instead of following hand-written rules. Today we open that box and ask: what does "learning" actually mean for a computer?
We'll use the same example as last time: a spam filter.
The four ingredients of machine learning#
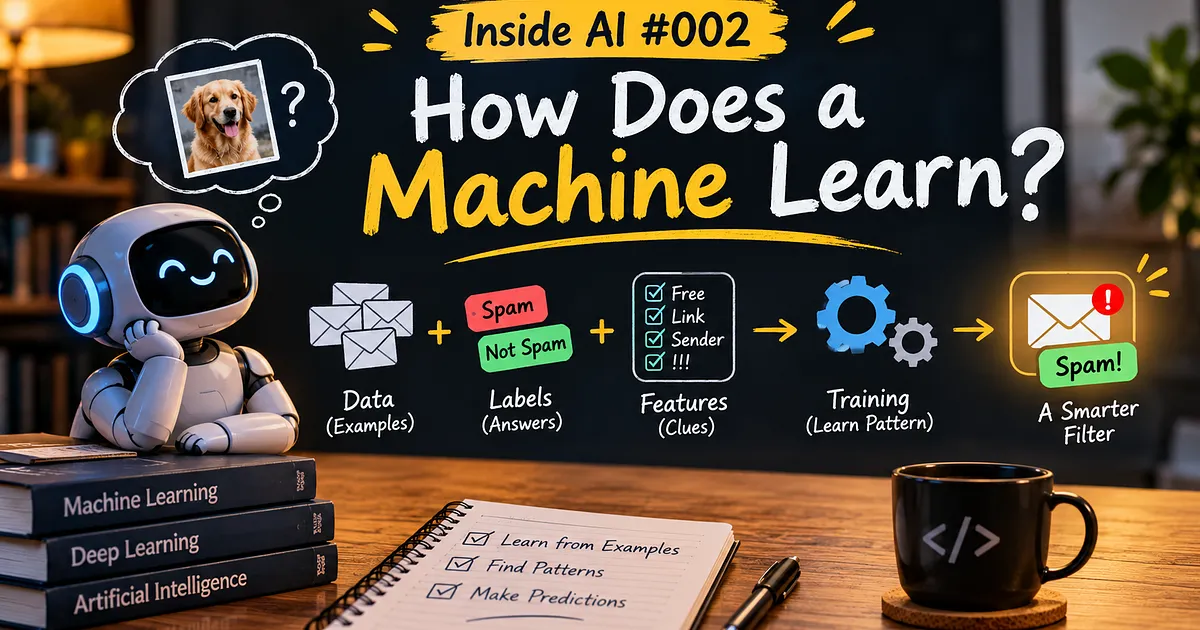
Every machine learning system, from a spam filter to ChatGPT, needs the same four things. Let's meet them with our spam filter.
1. Data: the examples#
Data is the pile of examples the machine learns from. For our spam filter, that's thousands of real emails.
Think of it as the dogs you saw as a child. More examples, and more varied examples, means better learning.
2. Labels: the correct answers#
A label is the right answer attached to each example. Every email in our pile is marked either spam or not spam.
Where do labels come from? Often from people like you. Every time you click "Report spam" in Gmail, you're labelling an example.
Label | |
|---|---|
"Congratulations! You won ₹10 lakh, click here" | Spam |
"Team meeting moved to 3 pm" | Not spam |
"FREE iPhone!!! Limited offer" | Spam |
"Your electricity bill for October" | Not spam |
3. Features: the clues#
The computer can't "read" an email like you do. So we turn each email into clues it can measure, called features. For example:
Does it contain words like "won", "free" or "offer"?
How many exclamation marks are there?
Is the sender in your contacts?
Does it have a link?
A feature is just a measurable detail. Like fur and barking for dogs.
4. The model: the learned pattern#
The model is what the machine produces after learning. It's the "recipe" that takes an email's clues and decides: spam or not spam.
Here's the key part: nobody writes this recipe by hand. The computer builds it from the data and labels. That building process is called training.
Training: guess, check, adjust, repeat#
Training sounds complicated, but it's a simple loop. Remember being corrected when you called a cat a dog? The machine goes through the same cycle, thousands of times.
   ┌──────────────┐
   │ 1. GUESS     │  look at an email, predict spam or not
   └──────┬───────┘
          ▼
   ┌──────────────┐
   │ 2. CHECK     │  compare the guess with the label
   └──────┬───────┘
          ▼
   ┌──────────────┐
   │ 3. ADJUST    │  wrong? tweak the model a little
   └──────┬───────┘
          ▼
   ┌──────────────┐
   │ 4. REPEAT    │  next email, again and again
   └──────┬───────┘
          └──────────► back to 1
Let's walk through it with our spam filter.
At the start, the model knows nothing. Every clue counts the same. It's basically guessing randomly, like a coin toss.
Email 1: "You WON a FREE prize!!!" (label: spam) The model guesses "not spam". Wrong. So it adjusts: the words "won" and "free" and lots of exclamation marks now count a bit more towards spam.
Email 2: "Lunch at 1?" from a friend in your contacts (label: not spam) The model guesses "not spam". Correct. Only a tiny adjustment needed.
Email 3: "Free pizza in the office today" from your colleague (label: not spam) The model sees "free" and guesses "spam". Wrong again. It learns that "free" alone isn't enough; a known sender pushes towards not spam.
Now repeat that with 100,000 emails. Each mistake nudges the model a little. Slowly, it discovers which clues matter, how much they matter, and how they combine.
The important idea: the model is never told the rules. It finds them by being wrong, and correcting itself, many times over.
Each full pass through all the training data is called an epoch. Models often go through the data many times, getting a little better each round.
How do we know it actually learned?#
Imagine two students preparing for an exam.
Student A memorises the answers to last year's paper, word for word.
Student B understands the concepts behind the questions.
Give them last year's paper and both score 100%. Give them a new paper and Student A fails, while Student B does well.
Machines can behave like either student. So we test them fairly.
The train/test split#
Before training, we split our emails into two groups:
Training set (about 80%): the model learns from these.
Test set (about 20%): hidden away. The model never sees them during training.
After training, we give the model the test emails and check how many it gets right. Because it has never seen them, this tells us how it will perform on real, new emails tomorrow.
Overfitting: when a model memorises#
When a model does brilliantly on training data but badly on new data, it's overfitting. Like Student A, it memorised instead of learning.
For example, if most spam in our training data happened to arrive on Tuesdays, an overfitted model might decide "Tuesday = spam". That's a coincidence, not a real pattern, and it would wrongly block your Tuesday meeting invite.
The usual fixes are simple to understand:
More and more varied data, so coincidences wash out.
A simpler model, so it can't memorise every detail.
Always judge on the test set, never on the training set.
The goal of machine learning is never to ace the practice paper. It's to do well on the questions it hasn't seen yet.
Three ways machines learn#
Our spam filter learned from labelled examples. But that's only one style. There are three main types, and each is like a different way humans learn.
1. Supervised learning: learning with a teacher#
The machine gets examples with the correct answers, like a student with an answer key. This is what our spam filter does.
Analogy: flashcards with the answer on the back.
Real examples: spam filters, predicting house prices, recognising handwriting, detecting fraud on your card.
2. Unsupervised learning: finding groups on its own#
The machine gets examples with no answers at all and is asked to find structure by itself.
Analogy: tipping a box of mixed buttons onto a table and sorting them into piles by colour and size, without anyone telling you the categories.
Real examples: an online store grouping customers with similar shopping habits, or a bank spotting transactions that look unusual.
3. Reinforcement learning: learning by trial and reward#
The machine tries actions and gets rewards or penalties. Over time it learns which actions lead to the best results.
Analogy: teaching a puppy to sit. Sits? Treat. Jumps on the sofa? No treat. The puppy figures out what earns rewards.
Real examples: game-playing AI, robots learning to walk, and part of how chatbots like ChatGPT were taught to give more helpful answers.
Type | Gets answers? | Learns by | Example |
|---|---|---|---|
Supervised | Yes | Comparing guesses with answers | Spam filter |
Unsupervised | No | Finding groups and patterns | Customer groups |
Reinforcement | No, only rewards | Trial and error | Game-playing AI |
Beneath the surface#
In #001 we said a trained model is just a file of numbers. Now you can see where those numbers come from.
Each clue ("contains free", "sender is a contact", "has 5 exclamation marks") gets a number that says how much it matters. These numbers are called weights. At the start they're random. Every "adjust" step in the training loop is simply a tiny change to these weights.
So when people say "the AI learned", what really happened is: millions of tiny number changes, each one fixing a small mistake. No understanding, no rulebook. Just numbers slowly moving in the right direction.
Recap#
Machine learning needs data, labels, features and a model. Training turns the first three into the fourth.
Training is a loop of guess → check → adjust → repeat, run thousands of times.
We test on data the model has never seen to make sure it learned instead of memorised (overfitting).
Coming up next#
AI from Zero #003: What Is a Neural Network? Those weights we just met live inside something called a neural network. We'll build a tiny one by hand, a single "neuron" that decides whether you should go out tonight, and see how stacking many of them creates deep learning.
If this helped, subscribe to the newsletter so you don't miss the next part of AI from Zero.